Case study / Knowledge + conversation
Alex.
Technical knowledge.
Answers you can inspect.
A locally hosted AI knowledge assistant that connects mixed technical records to searchable, source-linked answers.
Original conceptual architecture
Evidence first. Generation second.
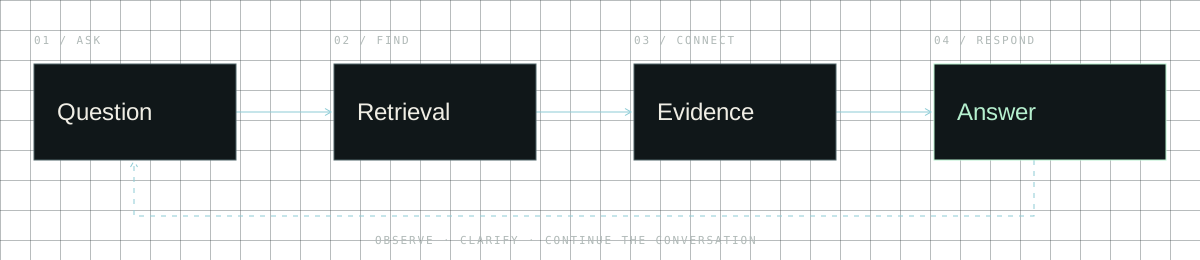
Ask
A question or exact reference sets the retrieval path.
Find
Literal matching and semantic similarity gather candidates.
Select
Deduplicated, ranked passages form a bounded evidence packet.
Inspect
The answer includes sources to check, not a guarantee of correctness.
01 / The problem
The information was there.
The useful evidence was harder to find.
Technical PDFs, Office documents, spreadsheet rows, maintenance records and narrative notes held different pieces of the answer. Finding a passage was only part of the challenge: its date, context and relationship to an original record still mattered.
Alex grew from document discovery and a Microsoft Copilot knowledge package into a custom retrieval-augmented generation application. It gathers relevant evidence before asking a language model to draft an answer. Updating that evidence does not require retraining the generator.
02 / My role
Connect the requirements.
Own the delivery decisions.
I directed the architecture and delivery across successive versions: framing the outcome, reviewing answers, challenging unsupported conclusions and deciding when a deployment could proceed. Collaborators supported data preparation; AI coding assistants supported implementation and review.
My custom-configured Lex AI assistant supported planning, implementation review and evidence checks. A bounded worker workflow recorded orders, results and escalation. Human review retained responsibility for material operational decisions.
03 / Engineering the evidence
Preserve the source.
Make the transformation traceable.
Intake preserved originals, verified copies with SHA256 checksums and rebuilt knowledge cumulatively. Extraction retained useful locations such as pages, paragraphs, spreadsheet rows and cells. When relevant spreadsheet evidence was missed early on, preserving complete row context was more useful than simply changing the model.
Structured metadata reconciled names and aliases without pretending uncertain associations were facts. Versioned chunking retained document structure and provenance. Historical repair accounts, approved references and unconfirmed observations remained distinguishable.
Deeper detail: reproducible corpus builds
Manifests controlled intake. Source hashes, document identities, redirects and derived chunk identities connected retrieval text to its lineage. Compact context headers helped passages remain understandable outside their parent documents. Difficult formats could be inventoried without claiming complete extraction.
04 / Retrieval design
Find exact terms.
Also search by meaning.
PostgreSQL full-text search supports identifiers and distinctive terms. BGE-M3 embeddings represent queries and passages as normalized 1,024-dimensional vectors; pgvector supplies cosine-similarity search. The documented V3.2.1 semantic build used an HNSW approximate-nearest-neighbor index.
Five quota lanes gathered troubleshooting, procedures and references, internal documents, logged episodes, and observations. This helped prevent a large historical-record category from crowding out a smaller reference category. Candidates were merged, deduplicated and reranked. Not every final answer necessarily included every source type.
Deeper detail: V3.1 and V3.2 did not use the same ranking policy
V3.1 combined lexical and vector ranked lists using Reciprocal Rank Fusion. The V3.2 baseline preserved lexical ordering for positive exact matches; other questions used semantic candidates followed by similarity and title-coverage reranking. This was a custom policy, not a separately trained neural reranker. A score threshold and parts of proposed document-level quotas still needed calibration or acceptance.
05 / Model integration
Keep the generator stable.
Test the surrounding system.
Python connected intake, search, answer integration and validation. Qwen generation was served locally through vLLM, with OpenWebUI providing conversational access. Search and answer services could evolve without changing model weights. This was application engineering around established models, not a foundation model trained from scratch or a documented project-specific fine-tuning run.
Deeper detail: the recorded serving recipe
Deployment records identify nvidia/Qwen3.6-35B-A3B-NVFP4 under the application alias qwen3.6-35b, on compact NVIDIA GB10-based hardware. Resource behavior, context limits, swap and concurrent requests were tested rather than inferred from model size. Docker and systemd supported operation; versioned changes, side-by-side routes and rollback definitions protected earlier working versions.
06 / Documented evidence
A bounded result.
Not a universal benchmark.
The documented V3.2.1 snapshot contained 28,313 curated documents and 128,823 retrieval chunks. These are build counts, not current inventory, model parameters or answer-accuracy figures.
The September acceptance record reports coverage for the curated document paths and 11 verified raw originals. Recorded source-delivery tests downloaded cited files and compared SHA256 identities. Citation grouping preserved answer reference numbers; missing originals used labelled curated-document fallbacks.
These are retained project findings, not independent tests rerun for this website. They establish specific source and build properties, not that every generated statement is supported or every historical record is correct.
Deeper detail: what evaluation did and did not show
Checks covered chunk identities, hashes, vector counts, exact-reference and semantic queries, citations and visible answers. Sampled self-search returned the source rows at first rank. Model comparisons used a fixed question set plus one-, five- and ten-user load trials. Qwen remained selected after the documented comparison; some Llama 3.1 8B answers supplied plausible but unsupported procedural guidance.
A small question set, live retrieval and differing concurrency settings limit comparison. Higher-load errors were recorded. No independent accuracy percentage, enterprise service level or measured financial return follows from these trials.
07 / Limits and next questions
Keep the judgment.
Make the boundary visible.
Local hosting offered control over the corpus and model-serving configuration. It did not establish complete access control, unlimited capacity or correct answers. Source relevance, operational context and human review remain essential.
Voice and predictive improvements are not delivered features
Voice interaction remains proposed. Using curated evidence with operating data to find performance opportunities is a future investigation, not a delivered predictive model or proof of efficiency improvement. Reliable metrics, comparable conditions and validated interventions would be prerequisites.
Basis and publication boundary
This narrative summarizes retained development and validation records from June through October 2026, through V3.2.1. It does not assert exact inception timing, unrestricted acceptance, a fresh production-health audit or completed human evaluation. The underlying writing source is private and is not offered as a download.
This new draft awaits factual and publication review.
The wider picture